Grounded, cited answers
Every response is built from retrieved passages and shows the exact sources — no unsourced guesses.
A RAG knowledge base and chat assistant that runs on your infrastructure. Upload documents, ask in plain language, and get answers grounded in your own sources — with citations, streaming, and voice. Local-first on Ollama, with optional Groq fallback.
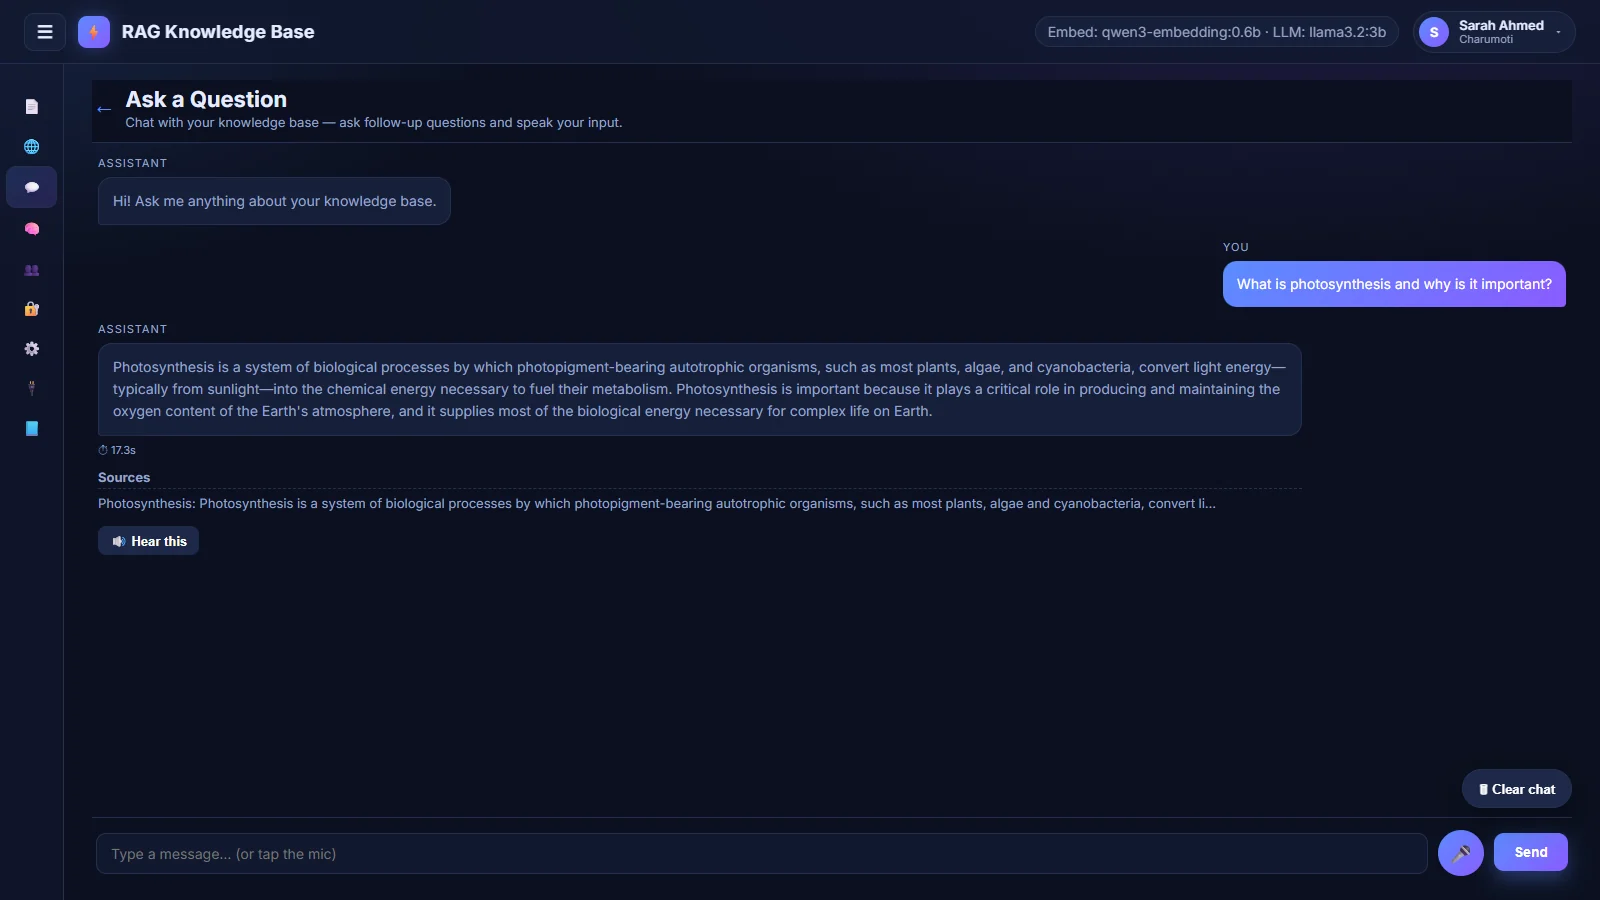
Ingest, retrieve, and answer — with the guardrails a real organization needs: tenant isolation, citations, and provider choice.
Every response is built from retrieved passages and shows the exact sources — no unsourced guesses.
Answers run on Ollama on your own hardware. Add Groq cloud fallback only when you want extra speed.
Vector search and PostgreSQL full-text search fuse with RRF, then FlashRank reranks the top candidates.
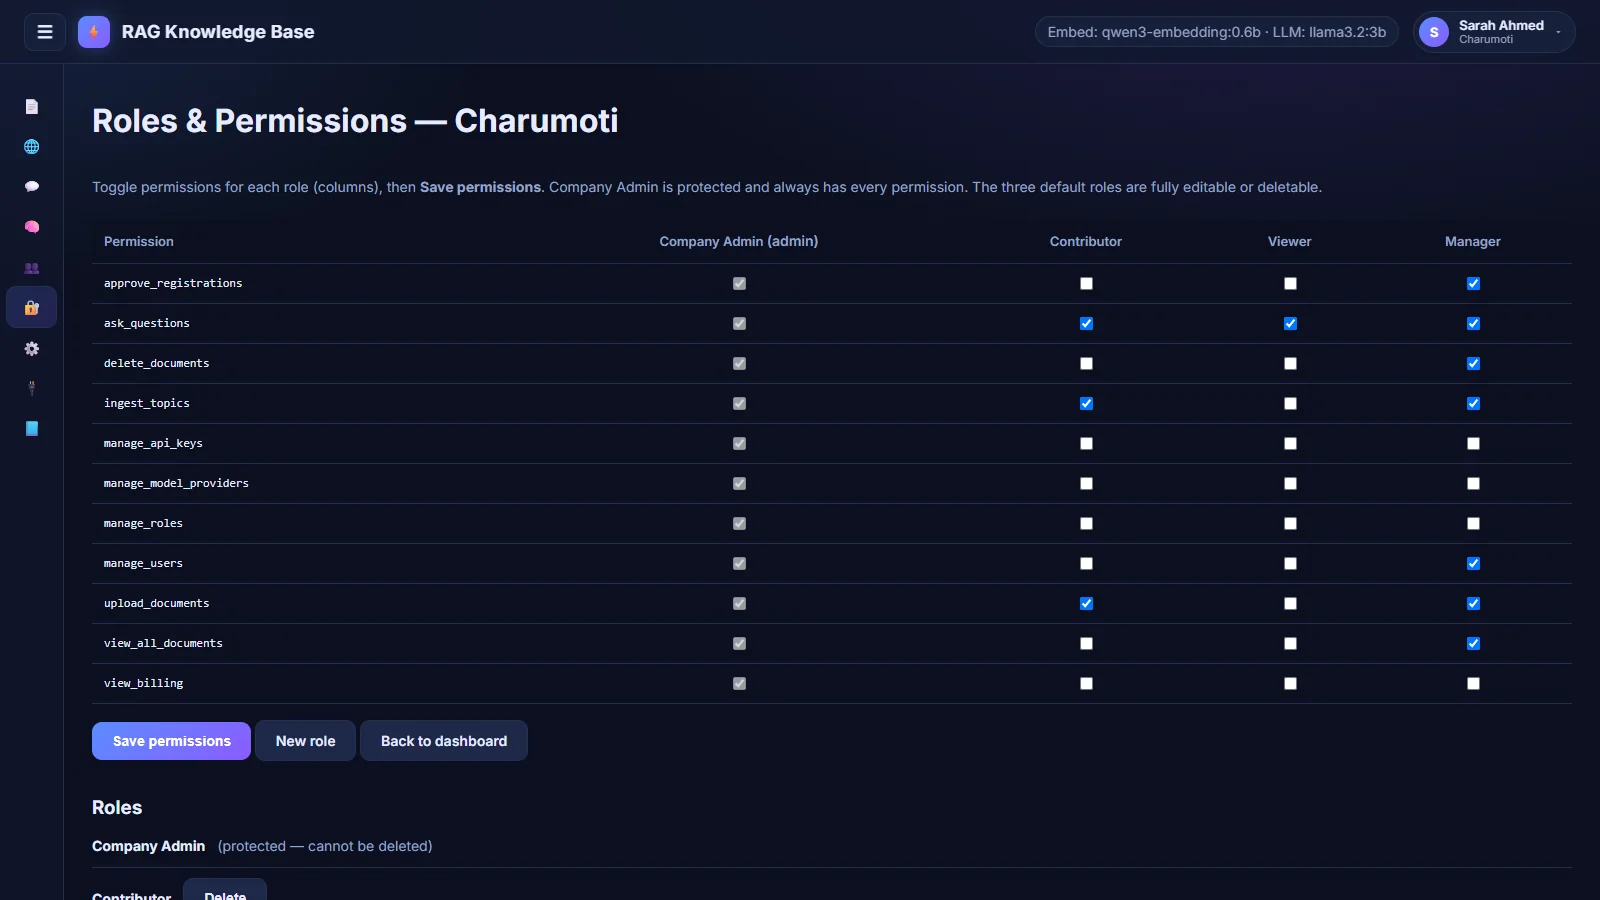
Companies, roles, and permissions isolate every tenant's documents, models, and API keys.
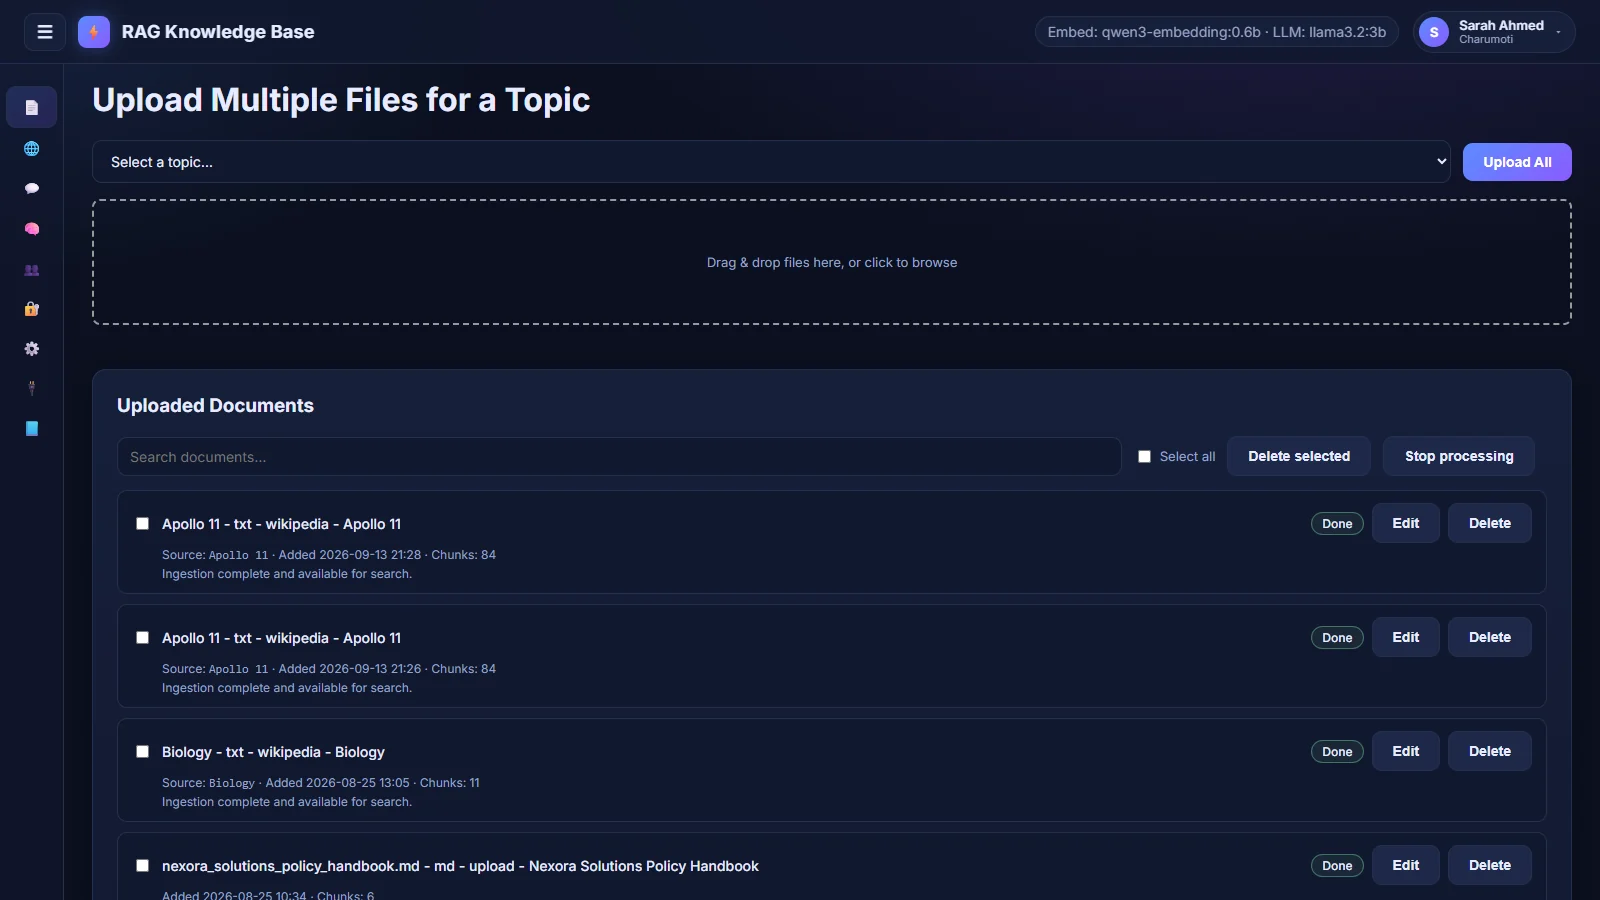
PDFs, Word docs, plain text, images with OCR, pasted content, web pages, and Wikipedia topics.
Token-by-token streaming keeps the UI responsive, and "Hear this" reads answers aloud.
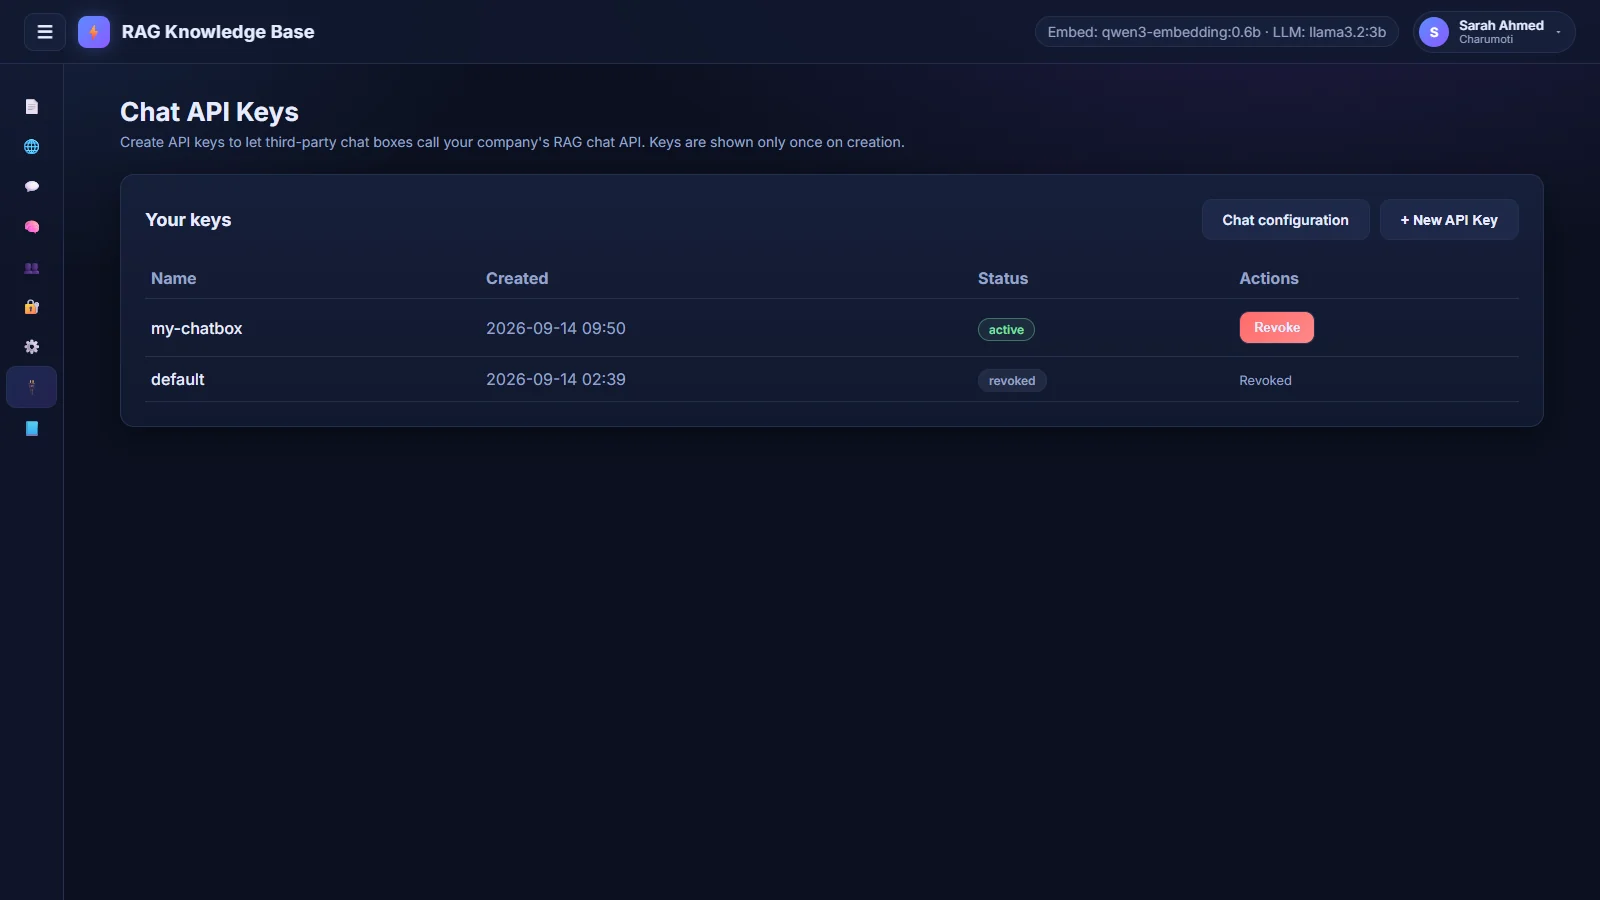
Per-company API keys with rate limits let you embed the assistant in any app or chat box.
Ollama, OpenAI, Anthropic, OpenRouter, or Groq — chosen per tenant, switchable at any time.
A transparent six-stage pipeline — the same one you can watch in the demo.
Upload files, paste text, or pull a URL or Wikipedia topic.
Text is extracted and split into overlapping passages.
qwen3-embedding:0.6b turns each chunk into a 1024-dim vector.
Vectors live in PostgreSQL + pgvector beside a full-text index.
Vector + keyword search, RRF fusion, then FlashRank.
llama3.2:3b answers from the top chunks, with citations.
The demo ships with a ready-made account for every role — including the platform Admin panel. Pick one and you're signed in.
Not mockups — captured from the running app.
Every layer is open source and replaceable. No vendor lock-in, no data leaving your network.
Multi-tenant models, role-based access control, and the admin panel in one framework.
Vectors and full-text search live in the same database as your business data.
Local generation and embeddings on your own GPU or CPU — no per-token billing.
Chunking, embedding, and retrieval orchestration with swap-in components.
A small cross-encoder that reorders candidates so the best passages reach the model.
Optional hosted models per tenant when you need speed beyond local hardware.
No signup, no credit card. Open the live demo and explore every role.